Headless CMS SEO: How to Rank Without a Plugin Safety Net
SearchBlueprint · · 15 min read · scored 89/100

Headless CMS SEO is the practice of making a decoupled site fully crawlable, fast, and indexable. In this setup, content lives behind an API and the front end is built separately. Three decisions matter most: your rendering strategy, your content model, and who owns metadata. No plugin makes those calls for you.
Get those three right and a headless stack usually outranks an equivalent monolithic site, mostly on speed. Get them wrong and Google may never see your content at all. This guide covers the full picture: rendering, Core Web Vitals, content modeling, structured data, sitemaps, redirects, migration, and the mistakes that quietly cost teams their rankings.
Key Takeaways
- A headless CMS is neither good nor bad for SEO by default. The front end you build determines whether search engines can crawl and index your pages.
- Rendering strategy is the single biggest ranking decision. Static generation (SSG) and server-side rendering (SSR) are safe. Pure client-side rendering (CSR) is risky, and dynamic rendering is now discouraged by Google.
- Every SEO element a plugin used to handle must be modeled as CMS fields and rendered by your front end. That covers titles, meta descriptions, canonicals, schema, sitemaps, and redirects.
- Editors need control over slugs, metadata, and redirects without filing a developer ticket. Otherwise your SEO velocity collapses.
- Audit the rendered HTML, not the CMS. What Googlebot receives is the only version that counts.
What Headless CMS SEO Actually Means

A headless CMS separates the content repository (the "body") from the presentation layer (the "head"). Contentful, Contentstack, Hygraph, Sanity, Strapi, and Kontent.ai all work this way. Your team writes content in the CMS. A separate front end, often built in Next.js, Nuxt, Astro, or SvelteKit, pulls that content through an API and turns it into HTML.
That split changes who does what. In a traditional CMS, a plugin like Yoast renders your title tags, generates your sitemap, and injects your schema. In a headless stack, none of that exists until someone builds it. Headless SEO is the discipline of rebuilding those guarantees deliberately, and often better than a plugin ever did.
Who Owns What Now
The ownership question trips up more teams than any technical detail. A workable split looks like this:
- Developers own the rendering layer: how HTML is generated, canonical logic, sitemap generation, redirect handling, and structured data templates.
- Editors own the inputs: titles, meta descriptions, slugs, alt text, and the content fields that feed schema.
- SEO leads own the requirements: which fields exist, which schema types apply to which content types, and what the audit cadence is.
If you're fuzzy on where these responsibilities sit in general, our breakdown of on-page, off-page, and technical SEO maps the same division for any stack. Headless just makes the technical column bigger and more explicit.
Why the "Headless Hurts SEO" Myth Persists
The myth survives because early headless builds were often pure client-side React apps that shipped an empty <div> to crawlers. Google's rendering of JavaScript has improved, but it's still slower and less reliable than parsing plain HTML. Vendors have pushed back hard on the myth. Contentful's own SEO guide (updated May 7, 2024, written by Senior SEO Manager Joshua Lohr and three colleagues) calls the "decoupling makes SEO harder" belief its number-one misconception. Hygraph published a similar myth-buster.
They're right, with a caveat: headless is SEO-neutral by architecture and SEO-positive only by implementation. The flexibility that lets you build a perfect stack also lets you build a broken one. Nothing warns you.
SSR, SSG, ISR, or CSR: Which Rendering Strategy Ranks?
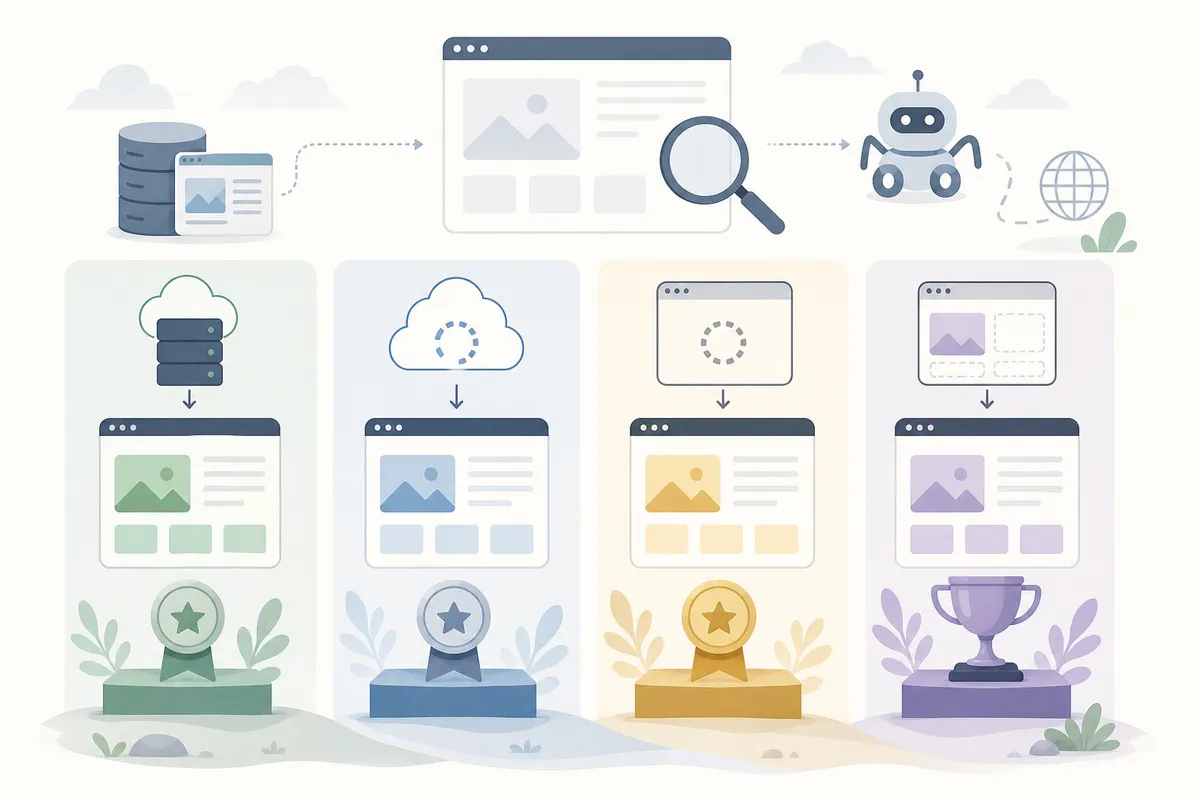
This is the decision that makes or breaks headless CMS SEO. Search engines rank what they can parse, and each rendering mode delivers HTML differently.
| Strategy | How It Works | SEO Impact | Speed Profile | Best For |
|---|---|---|---|---|
| SSG (static generation) | Pages are pre-built as HTML files at deploy time and served from a CDN | Excellent, crawlers get complete HTML instantly, no rendering queue | Fastest possible time-to-first-byte; great Core Web Vitals | Blogs, docs, marketing sites, content that changes daily or less |
| ISR (incremental static regeneration) | Static pages that rebuild individually in the background when content changes | Excellent, same crawler benefits as SSG without full-site rebuilds | Near-SSG speed with fresher content | Large catalogs, news sections, sites with thousands of pages |
| SSR (server-side rendering) | The server builds full HTML on every request | Very good, crawlers get complete HTML, at the cost of server response time | Slower TTFB than static; depends on server and caching | Personalized pages, live inventory, search results pages |
| CSR (client-side rendering) | The browser downloads JavaScript, then builds the page | Risky, content is invisible until JS executes; indexing can be delayed or partial | Slow first paint; heavy JS payloads | App-like interfaces behind login, never public content pages |
| Dynamic rendering | Bots get a pre-rendered version; humans get the JS app | Discouraged, Google now recommends against it as a workaround | Adds infrastructure complexity | Legacy stopgap only; migrate off it |
The Practical Default
For most content-driven sites, the answer is simple: static-first, server-rendered where freshness demands it. SSG or ISR for articles, landing pages, and product content. SSR for anything genuinely dynamic. CSR is reserved for interactive widgets inside an already-rendered page: a filter, a calculator, a carousel. Never use it for the page's primary content.
The test is equally simple. View source on any important URL. If your headline, body copy, title tag, and schema appear in the raw HTML before any JavaScript runs, crawlers can index you reliably. If the source is a script tag and an empty root element, you're gambling on Google's render queue.
Why Dynamic Rendering Is a Dead End
Dynamic rendering, sniffing user agents and serving bots a stripped, pre-rendered version, was once treated as an acceptable workaround. Google's guidance has since shifted to recommending against it. It resembles cloaking and adds a second version of your site to maintain. The official documentation at Google Search Central covers current JavaScript SEO recommendations. The short version: serving the same server-rendered or static HTML to everyone is both simpler and safer.
How CDNs and Static Generation Improve Core Web Vitals
Speed is where headless earns its keep. Kontent.ai's guide cites a Statista survey finding that 1 in 4 visitors will bounce from a site that takes more than 4 seconds to load. Core Web Vitals, Largest Contentful Paint, Interaction to Next Paint, and Cumulative Layout Shift, feed Google's page experience signals. Headless architecture gives you direct control over all three.
Where the Speed Comes From
- Pre-rendered HTML from a CDN edge. Static pages skip database queries and server-side template assembly entirely. The file already exists; the CDN nearest the visitor serves it. That alone typically drops time-to-first-byte dramatically compared to a plugin-heavy monolith.
- No template bloat. Traditional themes ship every page with the CSS and JS of every feature the theme supports. A custom front end ships only what each page needs.
- Image pipelines. Most headless platforms include on-the-fly image transformation, resizing, WebP/AVIF conversion, lazy loading. A 4MB editor upload never reaches a phone at full weight.
- Controlled JavaScript. You decide what hydrates and when. Frameworks like Astro can ship near-zero JS for content pages, which directly improves interaction metrics.
What Speed Doesn't Buy You
Be honest about the ceiling. Fast pages with thin content still lose to slower pages with better content. Contentstack's guide (published Sep 5, 2024, a 9-minute read) notes that organic search drives more than half of all trackable web traffic. But that traffic goes to pages that answer the query, not merely pages that load fast. Treat Core Web Vitals as a qualifier, not a strategy. This holds regardless of the platform you publish from. The fundamentals we cover across every major CMS and site builder don't change when the head comes off.
Turning CMS Fields Into SEO Signals
Here's the mental shift headless demands: you don't optimize pages, you optimize content models. A content model is the schema that defines what fields each content type carries. Miss a field at modeling time, and every editor is blocked until a developer adds it.
The Non-Negotiable SEO Fields
Every indexable content type needs, at minimum:
- Title tag, separate from the H1, with a sensible fallback if left empty
- Meta description, editor-writable, with character guidance in the field help text
- URL slug, editable by editors, validated against duplicates
- Canonical URL, defaulting to self, overridable for syndicated or variant content
- Robots directives, an index/noindex toggle per entry
- Open Graph image and text, for social and, increasingly, AI-surface previews
- Alt text on every image field, required, not optional
A common failure mode: developers hard-code titles from the H1 "to keep things simple." Six months later, the SEO team can't differentiate title tags from headlines anywhere on the site. Model the fields separately from day one.
Structured Data That Actually Validates
Structured data is a genuine headless advantage. Instead of a plugin guessing at your schema, you map CMS fields directly to Schema.org properties and render JSON-LD in the page head. An article model feeds Article schema: headline, author, datePublished, image. A product model feeds Product schema: name, price, availability, aggregateRating.
Three rules keep it clean:
- Generate schema from fields, never hand-write it per page. Field-driven schema stays accurate when content changes; pasted JSON-LD rots.
- Only mark up what's visible on the page. Schema describing content users can't see violates Google's structured data guidelines.
- Validate in CI, not after launch. A malformed date field format can silently invalidate schema across thousands of pages.
For stores, this mapping is where rich results live or die. Price, availability, and review fields flowing into Product markup is a core part of e-commerce SEO on platforms like Shopify and BigCommerce. The headless version of that job is identical, just self-built.
Programmatic Pages Without Duplicate Content
Content modeling also unlocks scale. Contentful's guide uses the example of a business with dozens of brick-and-mortar locations needing a landing page per location to capture localized searches. With a structured model, you generate all of them from one template while keeping each page genuinely distinct. Shared components carry the common parts; unique per-location fields like address, hours, staff, and local FAQs do the rest. That's the same pattern behind effective location pages and local rank tracking: the template scales, the local detail differentiates.
The trap is generating pages with only shared content. If 95% of each location page is identical boilerplate, you've built doorway pages, and Google's spam policies treat those harshly. Unique fields must carry real, unique information.
Sitemaps, Robots.txt, and Redirects Without a Plugin
In WordPress, these ship free with any SEO plugin. In a headless stack, each is a small engineering task. None is hard; all are forgettable, and forgetting them is expensive.
XML Sitemaps
Build the sitemap as a route in your front end that queries the CMS for all published, indexable entries at request or build time. Requirements worth writing into the ticket:
- Include only URLs that return 200 and are self-canonical
- Update
lastmodfrom the CMS's actual modified timestamp, not the build date - Split into a sitemap index once you approach the 50,000-URL per-file limit
- Exclude noindexed entries automatically, the noindex toggle in your content model should drive both the meta tag and sitemap membership
Contentstack's guide makes a point worth repeating: agree with your dev team how the sitemap updates before launch. A static sitemap generated once at build time goes stale the moment an editor publishes without a rebuild.
Robots.txt
A headless robots.txt is usually short: allow crawling, reference the sitemap, block genuine crawl traps like faceted search parameters or preview routes. The classic headless failure is the opposite, a staging Disallow: / rule that ships to production during launch week. Put a robots.txt check in your deploy pipeline.
Redirects
Redirects deserve their own field or content type in the CMS so editors can create them when they change a slug. The rendering layer (or edge middleware) reads that list and serves 301s. If slug changes don't automatically trigger a redirect from the old URL, every editorial rename silently 404s existing rankings. This is exactly the class of issue a technical SEO audit that orders fixes by impact surfaces fast. Broken redirect chains, orphaned URLs, and sitemap-canonical mismatches cluster on headless sites that skipped this step.
Common Headless SEO Mistakes That Cost Rankings
These are the recurring failures across headless builds. They're the practical version of what community threads like r/TechSEO circle around whenever the "headless CMS and SEO" question comes up.
| Mistake | Why It Hurts | The Fix |
|---|---|---|
| Shipping primary content client-side only | Crawlers see an empty shell; indexing is delayed, partial, or absent | Move content pages to SSG, ISR, or SSR; reserve CSR for widgets |
| No meta fields in the content model | Editors can't set titles or descriptions; everything falls back to defaults | Add title, description, canonical, robots, and OG fields to every indexable type |
| Hard-coded or missing canonical tags | Parameter and variant URLs split ranking signals across duplicates | Default canonical to self, render it server-side, allow editor override |
| Sitemap generated only at build time | New content stays invisible between deploys | Generate the sitemap dynamically from the CMS API, or trigger rebuilds on publish |
| Slug changes without automatic 301s | Old URLs 404 and their rankings evaporate | Store redirects in the CMS; fire one automatically on every slug change |
| Staging robots.txt or noindex leaking to production | The entire site drops out of the index | Environment-aware config plus a deploy-time robots and meta-robots check |
| Soft 404s from the JS router | Missing content renders a "not found" page with a 200 status, polluting the index | Return real 404/410 status codes at the server for missing entries |
| Schema hand-pasted instead of field-driven | Markup drifts from visible content and stops validating | Generate JSON-LD from CMS fields in the page template |
Two of these, CSR-only content and leaked noindex, account for most of the horror stories where a site "lost everything after going headless." Neither is a headless problem; both are launch-checklist problems.
Migrating to Headless Without Losing Traffic
If you're moving an existing ranked site to a headless stack, the migration itself is the riskiest moment. A disciplined sequence protects you:
- Crawl the current site first. Export every indexed URL, its title, meta description, canonical, schema, and internal links. This is your parity baseline.
- Map every URL. Keep URLs identical wherever possible. Where structure must change, build a complete 301 map before launch, not after rankings dip.
- Rebuild parity, then improve. Launch the headless site matching the old site's metadata and schema one-to-one. Optimize afterward, so you can attribute any movement to the migration rather than simultaneous changes.
- Diff rendered HTML. Compare what crawlers received before and after on a sample of top pages. Check titles, canonicals, schema, and internal link counts.
- Watch Search Console daily for the first month. Coverage errors, sudden 404 spikes, and dropping impressions are early warnings you can still fix cheaply.
Coming from WordPress specifically, inventory what your plugins were silently doing: redirects, image sitemaps, breadcrumb schema, RSS. Each is now a requirement someone must own. Teams staying on WordPress can lean on verified WordPress publishing workflows. Teams going headless need the same guarantees rebuilt by hand. And if you want to see what stack a competitor who made the jump is actually running, a free CMS detector reveals the CMS and front-end framework behind any URL in seconds.
Auditing and Monitoring a Headless Site
Headless removes the plugin dashboard that used to flag problems, so monitoring has to be deliberate. The principle: audit the output, not the CMS. The CMS can be perfect while the rendered site is broken.
What to Check, and How Often
| Check | What You're Verifying | Cadence | Signal of Trouble |
|---|---|---|---|
| Rendered HTML spot-check | Content, title, canonical, and schema exist in server response | Every deploy | Empty body or missing tags in view-source |
| Search Console coverage | Pages indexed vs. discovered; crawl errors | Weekly | "Crawled – currently not indexed" climbing |
| Core Web Vitals field data | LCP, INP, CLS from real users | Monthly | Regressions after front-end releases |
| Sitemap freshness | New publishes appear; removed pages drop out | Weekly | lastmod stuck at an old build date |
| Redirect integrity | Old URLs still 301 to live targets | Monthly | Chains, loops, or 404s in the redirect map |
| Structured data validation | JSON-LD parses and matches visible content | Every deploy | Rich results disappearing from SERPs |
Making It Sustainable
Manual checks decay. The deploys that break things are exactly the ones where everyone's rushed. Two habits keep headless sites healthy long-term. First, put SEO assertions in CI, a deploy fails if robots.txt blocks the site, if key templates render without titles, or if schema doesn't validate. Second, run a recurring external audit against live URLs. CI can't catch what happens after caching, CDN rules, and edge middleware touch the response. An AI SEO agent that runs the full loop from a single URL, crawl, prioritize, fix, verify, fits headless stacks well precisely because it evaluates the rendered output the way a crawler does, regardless of what's behind it.
When you report on all this to stakeholders, resist dumping raw crawl data on them. Our guide to what belongs in a professional SEO report covers how to frame technical findings as business risk. That matters double on headless projects, where fixes route through engineering sprints rather than a settings screen.
Where AI Search Raises the Stakes
One more reason rendered HTML matters in 2026: AI answer engines and Google's AI Overviews extract from what they can parse. Clean server-rendered HTML, self-contained passages, and valid structured data are exactly what gets quoted. A headless stack that nails these fundamentals is well-positioned for AI-driven discovery; one that hides content behind client-side JavaScript is invisible to it. Headless CMS vendors are leaning into adjacent territory too. Contentful, for instance, promotes AI content generation that can localize content in about 100 languages. But generation only pays off if the delivery layer exposes the result to crawlers and answer engines alike.
FAQs
Is a headless CMS bad for SEO?
No. A headless CMS is SEO-neutral by architecture, rankings depend entirely on how the front end renders content. Sites using static generation or server-side rendering, with metadata and schema modeled as CMS fields, routinely match or beat traditional CMS sites, largely on speed. Problems arise only when content is rendered client-side or SEO fields were never modeled.
Which rendering strategy is best for headless CMS SEO?
Use static generation (SSG) or incremental static regeneration (ISR) for most content pages. Use server-side rendering (SSR) for genuinely dynamic pages, and client-side rendering only for interactive elements inside already-rendered pages. Avoid dynamic rendering, serving bots a different pre-rendered version, as Google now recommends against it.
How do you handle sitemaps and redirects without an SEO plugin?
Build the XML sitemap as a route that queries the CMS for all published, indexable URLs, updating automatically on publish. Store redirects as entries in the CMS so editors can manage them, and have the server or edge layer serve 301s from that list. Both are small, one-time engineering tasks that replace what a plugin did.
Can content editors manage SEO in a headless CMS?
Yes, if the content model gives them the fields: editable slugs, title tags, meta descriptions, canonical overrides, alt text, and an index/noindex toggle. A well-built headless editing experience can match a plugin like Yoast. If those fields weren't modeled, editors are blocked on developers for every change, which is a modeling failure, not a headless limitation.
Does structured data work differently on a headless site?
The output is identical, JSON-LD in the page head using Schema.org vocabulary, but the source differs. Instead of a plugin generating markup, your templates map CMS fields directly to schema properties. That field-driven approach is usually more accurate than plugin defaults, because the markup updates automatically whenever the underlying content changes.
See What a Real Headless Audit Finds
The fastest way to know whether your rendering, schema, sitemaps, and redirects are actually holding up is to see them scored the way a crawler sees them. Headless CMS SEO problems hide in the output, not the editor. Browse a sample SEO report showing exactly what gets checked and how fixes are prioritized, then talk to the team about running the same audit on your own stack.
Resources / References
Sources
- Headless CMS and SEO : r/TechSEO
- Headless SEO Explained | SEO Guide
- Headless CMS and SEO Best Practices
- Headless CMS SEO: Your path to superior online rankings
- Mastering SEO with a headless CMS
Disclaimer: This article is general information about rules and figures that applied when it was written, not personalised financial, tax or investment advice. It does not take account of your income, obligations, risk tolerance or goals, and rates and thresholds change. Verify the current position with the relevant authority, and speak to a licensed adviser or a qualified accountant before acting.
About the author
SearchBlueprint researched, wrote and scored this article with the content pipeline our customers run on their own sites. The score in the byline is what our content engine gave this page before it published. Nothing here is reviewed by hand, which is the point: it is the product's output, published where anyone can check it.